Multi-tenant ERP
An ERP from scratch (finance, accounting, accounts payable and HR) built to hold more than one client in the same database without leaking a single row between them.
The problem
A small company that buys an off-the-shelf ERP pays for modules it never uses and cannot change anything. A company that commissions a custom one pays a lot and stays locked to whoever built it. I wanted to understand what sits in between: a system where each client is a tenant in the same database, with the same modules, and the difference between them is configuration, not code.
The interesting part is not writing the screens. It is that the moment two clients share a database, every programming mistake becomes one client’s data leaking into another’s. That is the real problem of this project, and it is what the decisions below are about.
Technical decisions
A global tenant filter that fails closed, not open
Against what: repeating WHERE tenant_id = @x in every query, which was the earlier design, and a global filter that, with no tenant resolved, released every row of every tenant.
Today the DbContext applies an automatic filter to every entity implementing ITenantScoped. With no tenant in context, the query returns nothing: instead of returning everything.
What it cost: anyone who needs a deliberate cross-tenant read now has to write IgnoreQueryFilters() explicitly, with a comment next to it saying why that read crosses tenants; an architecture test breaks the build if the comment is missing. More friction on the rare path, in exchange for making the common mistake impossible. The design-time factory runs with no context and therefore filters everything out; that is harmless because design-time only runs migrations, but it is exactly the kind of corner that has to be documented in the code itself so nobody “fixes” it wrongly later.
One attribute per controller, which both declares and enforces the permission
Against what: every action rewriting its own access check.
Discipline failed in practice: there was a commit that leaked precisely because it trusted the existing check, not because someone disabled it. So authorization became a single attribute at the top of the controller, [TenantModule("HR.Employees")], declaring which resource that controller exposes and gating it on the same line.
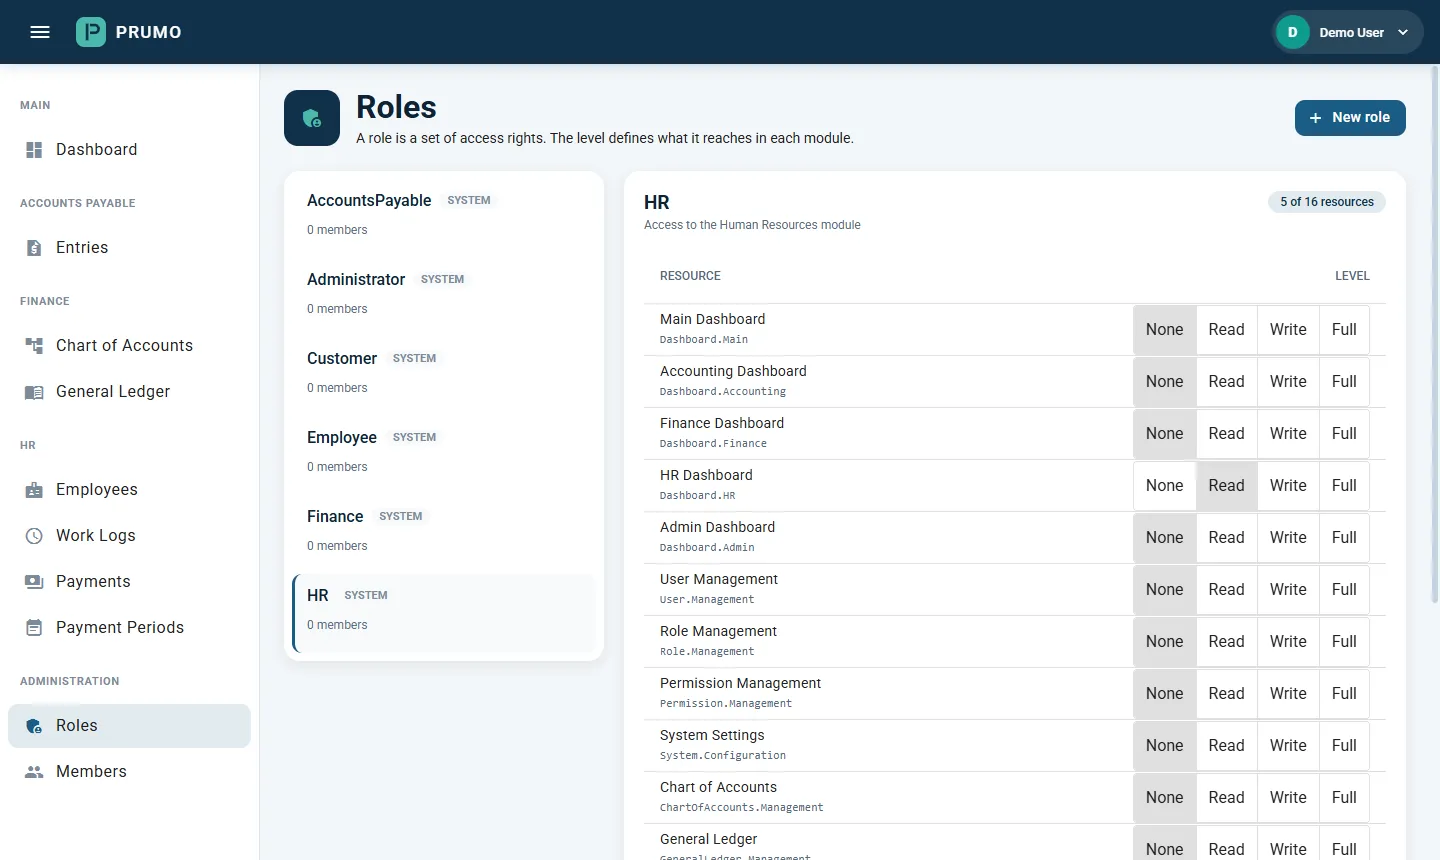
What it cost: data is read by the tenant in the route (api/tenants/{tenantId}/…), so that is the tenant the attribute proves membership against, and a token selected for another tenant gets a 403. Authorizing against one tenant and reading from another is worse than not authorizing at all. That means route and token are now coupled, and a client that builds the “wrong” URL gets an error instead of data.
An architecture test that breaks the build when someone forgets
Against what: trusting code review to remember the attribute.
A test walks the controllers and fails if any action under {tenantId} was left without the gate. A new endpoint written carelessly does not get through.
What it cost: and this is the part almost nobody writes down: the test catches forgetting, not getting it wrong. A second test rejects resource codes that do not exist in the catalog, but an employees controller declaring HR.Payments, a code that exists and is the wrong one, passes both and stays wrong. The net catches the person who forgot, not the person who wrote nonsense. And knowing exactly where the net has a hole is the difference between having protection and assuming you do.
The API connects as a database user that cannot change the schema
Against what: the API connecting as postgres, which is how it was.
A superuser ignores every permission check: one stray DROP SCHEMA public CASCADE takes all 25 tables with it, and no grant stops it. Today there are two database users: one that owns the tables and is the only one that runs DDL, and one that only reads and writes data. The API connects as the second. Transferring ownership of the tables was half the work, not a detail: revoking CREATE while the application still owned the tables would have left DROP TABLE just as open.
What it cost: the API stopped running migrations by itself on startup, because that was what forced it to hold DDL rights. Migrating became a separate deploy step. And so that a stale schema does not break later somewhere that does not explain the cause, the API checks for pending migrations on startup and refuses to serve, naming the command to run. A deploy that forgets the migration now does not come up, instead of coming up broken.
One fixed-cost machine, not a service that scales to zero
Against what: the first version, which ran end to end on Azure: Container Apps, ACR, Key Vault and managed PostgreSQL, scaling to zero when nobody was using it.
Container Apps charges for cold starts, and managed PostgreSQL has a price floor that no amount of idleness lowers. The current design is on AWS: one 2 GB Lightsail instance in São Paulo running four containers with docker compose (Caddy for TLS, the Angular nginx, the API and PostgreSQL 17), with images in ECR, pushed by GitHub Actions through OIDC, with no AWS key stored in the repository. About US$ 14 a month, fixed.
What it cost: it is a single machine, without the redundancy a managed service would give. It is the right shape for a system that is just starting, not for scale.
What was left out
Caching. There was a Redis module written, working and wired to nothing: the API had an ICacheService that nobody ever injected. I preferred deleting it to pretending it was part of the system. It comes back when caching earns its own cost.
The Azure version was torn down. The AWS one is all Terraform, and every pull request goes through fmt and validate against the real provider before it gets in.
The ERP has its first client, and that is why the code is no longer public.
[Stack]
- .NET
- PostgreSQL
- Angular
- Terraform
- AWS
- Docker
[Links]